AEO for B2B SaaS: The Pages AI Cites and the Metrics That Actually Track Pipeline


Popular Articles


TL;DR
- AEO for B2B SaaS is won on pages you own, because answer engines assemble software shortlists from alternatives, comparison, use case and industry pages rather than thought leadership.
- Your citation competition is Reddit, G2, Capterra and vendors who published their own honest listicles first.
- Visibility at informational prompts has close to zero relationship with demos booked. Track in-market prompts only.
- Prompt trackers cannot see most of the buyer journey, so build the on-site foundation before buying a dashboard.
- Off-site citations are earned through direct human outreach far more reliably than through paid listicle placements.
Most B2B SaaS teams investing in AEO are measuring a chart that has no connection to their pipeline. Their AI visibility score climbs, the leadership gets pleased but demo volume stays exactly where it was. Sam Dunning's diagnosis is uncomfortable for anyone who bought a prompt tracker before they built the pages.
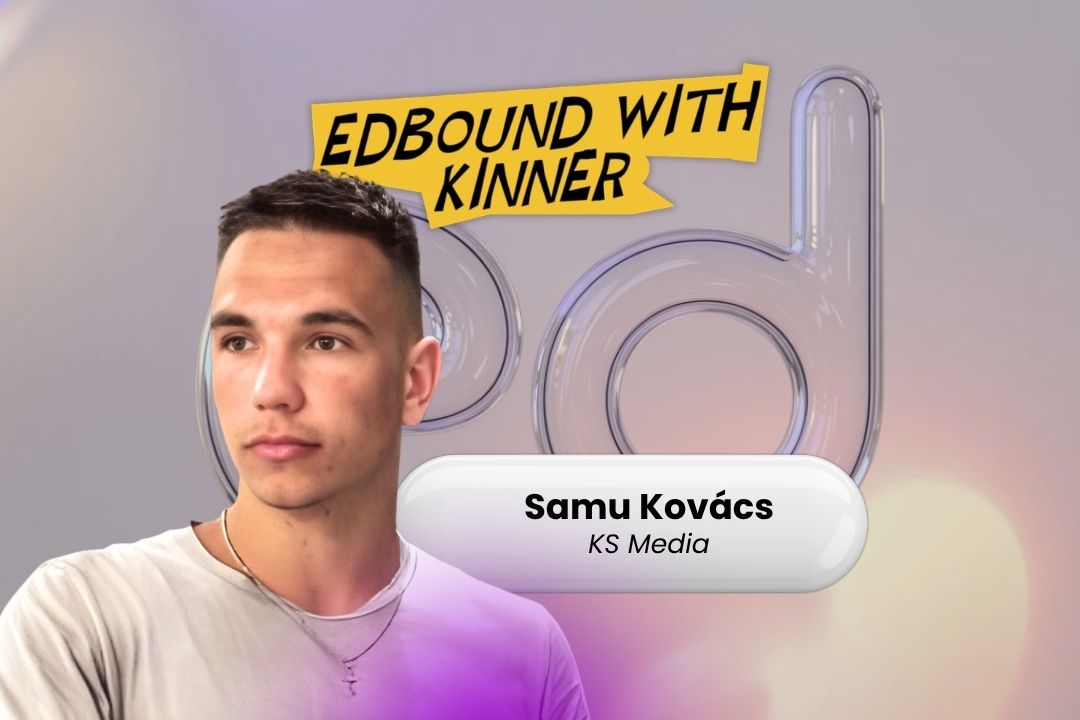
On the Edbound With Kinner podcast, host Kinner Sacchdev pushed Sam Dunning, founder of Breaking B2B and an SEO partner to roughly 43 active SaaS companies, through a genuinely combative hour on SEO, AI search, and where the money actually sits. He also hosts the Breaking B2B podcast, where he has interviewed close to 500 B2B marketers over six years. He built the agency's own inbound engine using the exact playbook he shares here.
How AI Search Builds a B2B Software Shortlist
Wynter's 2026 survey of 101 mid-market SaaS CMOs found that 84% now use AI tools for vendor discovery, with 68% starting there before Google. That is where your shortlist is decided.
Watch what happens when a VP of Sales asks ChatGPT for software. The prompt carries constraints: category, headcount, price ceiling, a specific use case. The model returns three to five named vendors.
That output is assembled from a narrow set of sources. Sam's observation from watching bottom funnel prompts is consistent: review platforms, Reddit threads, and vendor sites that host their own well-researched listicles.
Nobody in that shortlist got there through a top funnel explainer. They got there because a page existed that matched the shape of the question. This is the same mechanic behind how AI search visibility compounds from bottom funnel pages, and it reframes the entire AEO brief.
The buyer then arrives at your homepage directly. Your analytics records a direct visit. The evaluation happened somewhere you cannot see, which is the zero click search shift Rand Fishkin has been documenting for years, now accelerated by AI answers.
The Money Keyword Matrix That Decides Which Pages Get Cited
Sam builds every engagement from a four-column sheet he calls the money keyword matrix. It runs on customer research rather than keyword tools.
The money keyword matrix has four columns:
- Column one: every way a buyer names your category or solution.
- Column two: the industries you have genuinely sold into, with budget and urgency. Sam calls these money niches.
- Column three: the three or four competitors that surface on every sales call.
- Column four: your buyers' jobs to be done and their struggling moments.
Column four is where most teams go thin. The jobs to be done framework exists precisely because buyers describe outcomes, not features, and their language is sitting in your sales call transcripts already.
Cross those columns and you get long tail queries with obvious commercial weight. Competitor alternatives. Competitor pricing. Competitor reviews. Best category software for a named vertical. Integration-specific searches. Most carry keyword difficulty near zero and volumes under a hundred a month.
Low volume looks unserious on a forecast. Sam's counter is about who is typing it.
"no one searches for that stuff for fun. Like I'm not searching for a SaaS alternative for a pastime."
Somebody running that query has a live problem with an incumbent vendor. Fifty of those a month outperforms five thousand visits from an informational post, and the arithmetic holds in AI search because those are the prompts models resolve into named recommendations.
Page Intent Decides Whether an Answer Engine Cites You or Skips You
Having the keyword is half the work. The other half is shipping the page format the query expects, which SEOs call page intent.
Search "competitor alternatives" and the results are listicles. So a listicle is what you publish, and it has to survive scrutiny from both a reviewer and a model:
- A short summary near the top.
- A comparison table of the leading options.
- A why trust us section with your research method.
- Honest fit and poor fit notes for every tool, yours included.
- Transparent pricing, real screenshots, third party reviews.
Sam's warning about the failure mode is specific. Pages where three quarters of the text praises the vendor and competitors receive an X in every column get flagged, and pages generated wholesale by AI fall under Google's scaled content abuse policy. The upward traffic charts on LinkedIn rarely include the screenshot from three months later.
The reason to do this properly extends past rankings.
"I'd rather control the narrative with content from my own website than a disgruntled user on Reddit saying something that may or may not be true." Sam Dunning
That is the strategic case for citation work. Someone is going to define your product inside an AI answer. Publishing a fair, thorough, genuinely useful comparison makes it more likely to be you. The same logic drove Navattic's approach to content-led GTM, where owned assets carried the evaluation.
Beyond listicles, the same standard applies to dedicated pages for every industry, use case, integration and ICP you serve. Each one is a separate line in the water for a separate prompt.
Why AI Visibility Dashboards and Pipeline Disagree
Here is where a large share of AEO budget currently goes wrong. Companies arrive at Sam already subscribed to a prompt tracker, fixated on an overall visibility percentage.
The problem is prompt selection. Much of what those dashboards monitor is top funnel and informational. A model naming your brand when somebody asks a general question about your category tells you very little about revenue.
The prompts worth tracking for bottom funnel AEO are the ones a buying committee types when it is already in market:
- Best category software for a specific vertical or headcount.
- Alternatives to a named incumbent.
- Comparisons between two vendors you compete with.
- Integration and use case specific requirements.
- Migration and switching queries.
Two structural limits make prompt tracking softer evidence than the dashboard implies. Individual prompts are near-infinite in variation, and results shift with each user's history and context. The same query genuinely returns different vendors for different people.
Sam is candid about what that means for the category of self-appointed experts, himself included, and it is the most useful sentence in the episode for anyone evaluating an AEO vendor.
"so much of it is untraceable unless you put into play certain things."
This is the zero click evaluation journey in practice. The research happens inside the model, the click arrives as direct traffic, and the causal chain is invisible.
The board slide is three lines: in-market prompt coverage, citation presence on your five highest-intent pages, and direct traffic to those same pages. Everything else is context.
The operational response is to stop treating visibility as the outcome. Report on in-market prompt coverage, citation presence on the pages that matter, and the pipeline metrics your CFO already trusts: demo requests, trial starts, direct traffic to money pages, self-reported attribution on forms.
Earning Citations Off Site Without Buying Listicle Placements
Owned pages take you a distance. Getting cited across the sources models already trust needs off-site work, and this is where the market is at its most extractive. Paid placements on third party listicles are routinely sold by position, with the number one slot priced higher than the number two.
Sam's alternative is unglamorous and repeatable. He rebuilt Breaking B2B's own visibility from close to nothing using it:
- Publish your own honest listicle for the target query first.
- Find the competing listicles that rank and get cited.
- Identify the author on LinkedIn.
- Send a short, human connection note. Two lines, no pitch deck.
- Follow with a Loom walking through their article and proposing a mutual feature swap.
He ran a parallel version across podcasts, sourcing shows through a podcast directory, filtering to B2B and SaaS marketing, and pitching hosts the same way. Each booking returned reach, a brand mention, and a backlink to a money page. Guest appearances compound in a way single placements do not, and the mechanics of how one earned mention gets you cited in ChatGPT explain why models pick these up quickly.
The pattern interrupt is the whole method. Buyers of these placements send walls of text. A two-line note and a Loom stands out enough to get a reply.
The Build Order: What to Ship First
AI belongs in this system as an amplifier for research and drafting. It does not belong anywhere near unreviewed publishing, which is the fastest route to a penalty.
Weeks one to four: the foundation
- Interview ten customers. Recent wins and recent churn. Churned accounts give you the honest version.
- Load the transcripts into a knowledge base. Sales calls, support tickets, win-loss notes. This becomes the source of truth for buyer language.
- Build the money keyword matrix. This is the spine of bottom funnel AEO for B2B SaaS, and it runs on customer research rather than keyword tools. Four columns, cross-referenced into long tail queries.
- Score and sequence. Highest commercial intent against lowest difficulty. Competitor alternatives and pricing queries usually sit at the top.
- Ship the first three pages. One competitor alternatives listicle, one head-to-head comparison, one industry landing page.
Weeks five to twelve: proof and reach
- Answer objections on the page. Pull the recurring questions from sales calls into FAQ sections.
- Publish pricing or a range. Buyers arrive educated and screen on cost. Hiding it removes you from the shortlist.
- Shorten the path to an expert. Book time with someone who can answer technical questions, without a three-stage handoff.
- Run the outreach loop. Listicle placements and podcast appearances, in parallel, weekly.
- Instrument what is trackable. In-market prompt coverage, citation checks on your money pages, direct traffic, self-reported attribution.
Sam frames the compounding layer as a trio working together: founder-led LinkedIn organic, paid amplification of that same content, and YouTube built for search intent rather than used as a dumping ground. Each one feeds the pool of branded searches and direct visits that answer engines and buyers both read as authority signals.
Common Questions About AEO for B2B SaaS:
How do you get a B2B SaaS brand cited in ChatGPT?
Publish the page formats answer engines pull from when buyers are in market: honest alternatives listicles, head to head comparisons, and use case pages. Then earn mentions on the third party listicles already cited in your category. Owned pages come first, because they are the only source you control.
Is AI search visibility worth the investment for early stage startups?
It depends on whether buyers already search for your category. AI search collects existing demand rather than creating it. A startup in an established category with a named competitor set can justify the spend. Teams creating a new category see better returns from education and community first.
How can you tell if your content is being picked up by LLMs?
Run your in-market prompts manually across ChatGPT, Claude and Perplexity, and log whether your pages get cited by name. Pair that with direct traffic to your money pages and self reported attribution on demo forms. Prompt trackers add breadth, though results shift by user and session.
Do aggregator blog citations improve LLM mentions?
Placements on listicles that models already cite can help, because those pages are active citation sources. The value depends on whether the listicle ranks and gets pulled for your buyers' prompts. Buying position on low quality aggregators rarely moves anything and carries reputation risk.
Conclusion
The teams winning bottom funnel AEO for B2B SaaS are not running a different playbook from good SEO. They are running it with sharper intent selection, more honest comparison content, and reporting that survives a CFO's questions.
Start with the pages your buyers' prompts resolve to. Publish comparisons fair enough to be cited by a model that has no loyalty to you. Measure the prompts that carry purchase intent and ignore the rest.
That level of publishing consistency is where most teams stall, because the research, the drafting, the distribution and the tracking sit in four different places. Edbound AI brings the content engine, the distribution, and the pipeline signal into one system, so your comparison pages, podcast episodes and industry content ship on schedule and the demand they create is visible rather than guessed at. Execution at scale, without the burnout that kills most content programmes by month four.